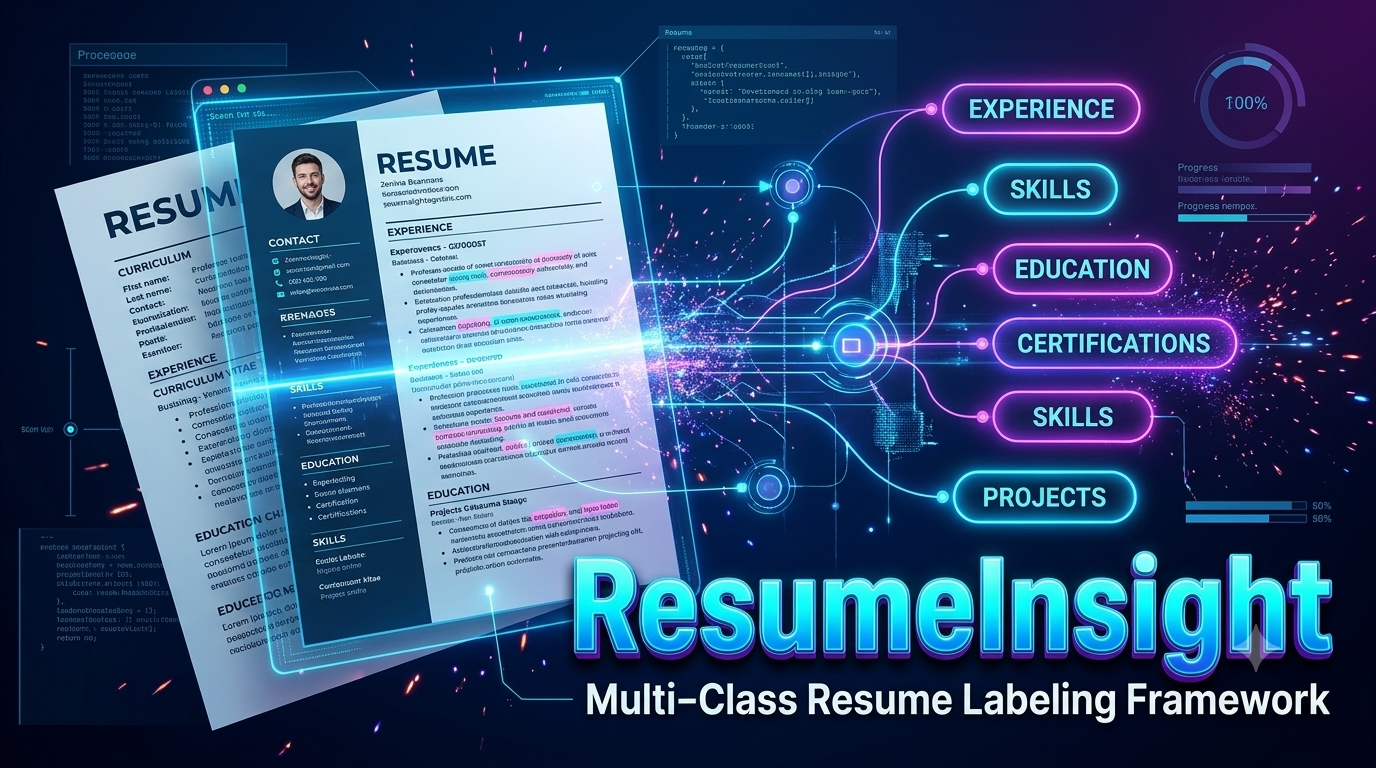
ResumeInsight: A Robust Text Mining Framework for Multi-Class Resume Labeling
ResumeInsight is a scalable machine learning system designed to automatically categorize professional resumes into diverse industry sectors with high precision. Built on a Ran...
$ 59.00
Quality Guaranteed
Reviewed project files and clear structure.
24/7 Support
Reach us anytime for setup and usage help.
Instant Access
Download your files right after checkout.
Source Included
Code, assets, and project-ready materials included.
About This Product
ResumeInsight: A Robust Text Mining Framework for Multi-Class Resume Labeling
Description
ResumeInsight is a scalable machine learning system designed to automatically categorize professional resumes into diverse industry sectors with high precision. Built on a Random Forest Classifier and powered by TF-IDF (Term Frequency-Inverse Document Frequency) vectorization, the model extracts critical professional keywords—such as technical skills, job titles, and experience markers—to identify the appropriate career category across a wide range of industry datasets.
It is optimized for recruitment automation, handling various document formats (CSV and PDF) and inconsistent text structures. Due to its efficient design and robust preprocessing pipeline, ResumeInsight is well-suited for HR tech platforms, automated screening tools, and large-scale talent acquisition systems.
Input
- Dataset: Raw resume text from CSV files or extracted text from PDF documents.
- File Upload: Individual resume files in PDF format.
Output
- Categorization: Detected industry class (e.g., Information Technology, Business Development, Designer, etc.).
Key Features
- Multi-Source Data Integration: Seamlessly combines structured CSV data with unstructured text extracted from PDF files using PyMuPDF.
- Advanced Text Preprocessing: Cleans and standardizes raw text by removing URLs, non-ASCII characters, punctuation, and extra whitespace to improve signal-to-noise ratios.
- High-Accuracy Ensemble Learning: Utilizes a Random Forest Classifier (with 100 estimators) to achieve robust and stable classification performance.
- TF-IDF Feature Extraction: Employs a vectorizer with a 3,000-feature limit and English stop-word removal to highlight the most relevant professional terminology.
- Automated Evaluation: Generates detailed performance metrics, including Confusion Matrices and Classification Reports (Precision, Recall, F1-Score).
- Deployment Ready: Exports the trained model, TF-IDF vectorizer, and label encoder as .pkl files for easy integration into web or mobile applications.
Tags
#ResumeInsight #TextMining #MachineLearning #NLP #ResumeClassification #RandomForest #TFIDF #HRTech #Automation #ScikitLearn #DataScience
References
1.Bhawal, S. (2025). Resume Dataset via Kaggle for multi-class classification.
2.Pedregosa et al. (2011). Scikit-learn: Machine Learning in Python (Random Forest and TF-IDF implementation).
3.Breiman, L. (2001). Random Forests research guiding the ensemble model architecture.
Backend Programming Language
Python
Backend Web Framework
Django
Frontend Structure
HTML
Frontend Styling
CSS
No reviews available for this product.